Auto Triage
Role: Administrators.
Platform: SaaS only.
Minimum Version: Ivanti Neurons for ITSM 2026.3.
Feature Eligibility: Ivanti's AITSM capabilities are available to customers who have subscribed to Premium or Enterprise Premium license. To know your eligibility, reach out to your Ivanti Account Manager.
Prerequisites:
- Raise an IT ticket to Ivanti Operations to set the ITSMTCPredictions feature flag in ConfigDB to Unconditionally On. By default, it is in Disable state. For further help, contact Ivanti support.
- ITSMTCPredictions in Unconditionally On state - The Auto Triage feature functions through ITSM AI services.
- ITSMTCPredictions in Disable state - The Auto Triage feature functions through Ivanti Neurons.
Auto Triage is an AI-powered ticket classification feature that automatically predicts and populates Incident fields such as Category, Subcategory, Service, and Team based on the information entered in the incident ticket. It uses a multilingual AI model and can process tickets submitted in any supported language.
Auto Triage includes the following key processes:
Training (configured by the administrator): Select the Input Fields, Output Fields, and a historical training data range. The system uses previously classified incident records to train the AI model and learn how to classify tickets. After training is complete, deploy the model to start predicting values for new tickets.
Prediction (for new and updated tickets): When a ticket is created or updated by an analyst, a self-service user, or through email, the model analyzes the values entered in the configured Input Fields (in any supported language) and predicts the values for the configured Output Fields. If the prediction confidence meets the configured threshold, the application automatically populates the predicted values and displays an AI Recommended label. Analysts can review and modify the predicted values before saving the ticket.
You can control prediction behavior by configuring confidence thresholds, stop words, and whitelisted keywords. Analysts can also override AI-recommended values when needed.
- At least 10,000 records must remain after preprocessing, which removes incomplete or low-quality records and rare labels with fewer than approximately 200 examples per class. To help meet this requirement, start with approximately 15,000 to 20,000 resolved or closed incidents and include additional records for categories with limited data.
- Auto Triage learns from your historical tickets and predicts and pre-populates classification fields for new tickets in any supported language, while confidence thresholds and analyst override options help you maintain control over the predictions.
To learn more about Auto Triage use cases, refer to the Using Auto Triage.
Enable Auto Triage
- Log in to Neurons for ITSM as an Administrator.
- Open the Configuration console > Build > AI Configuration Hub > AI & ML.
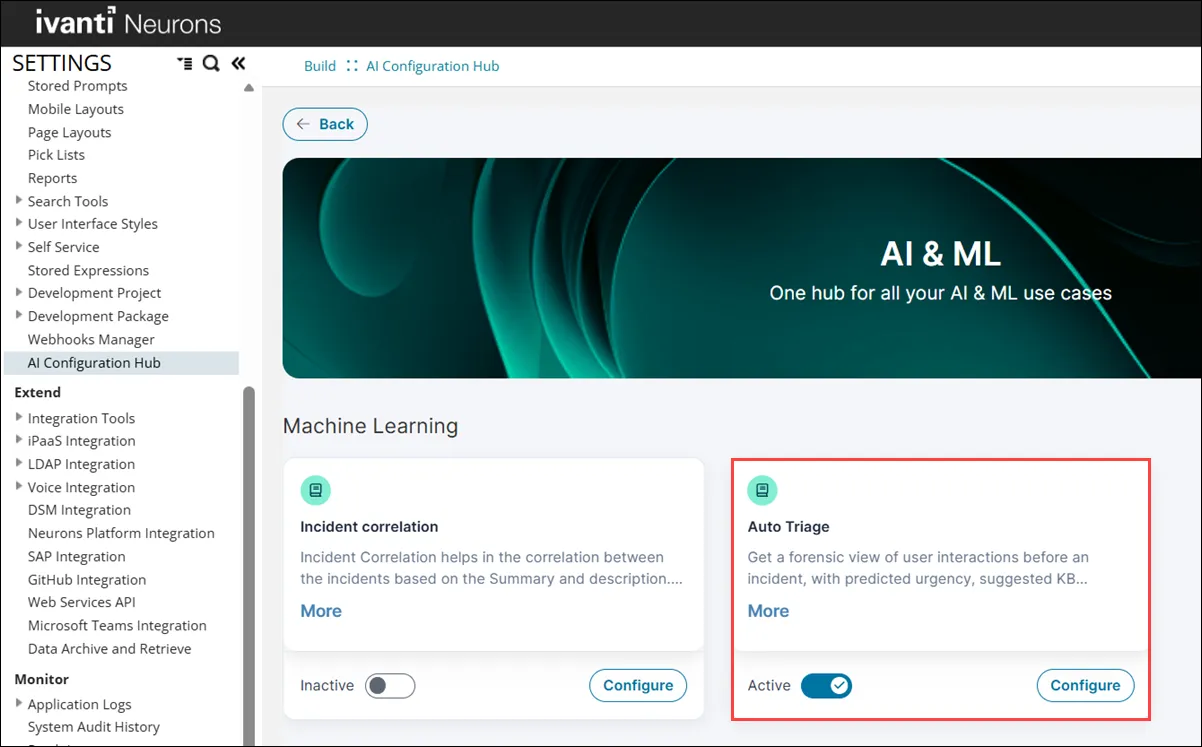
- Use the toggle to set Auto Triage to Active.
Configure Auto Triage
- Log in to Neurons for ITSM as an Administrator.
- Open the Configuration console > Build > AI Configuration Hub > AI & ML.
- Select the Configure option beside the toggle button.
- Select Add Model.
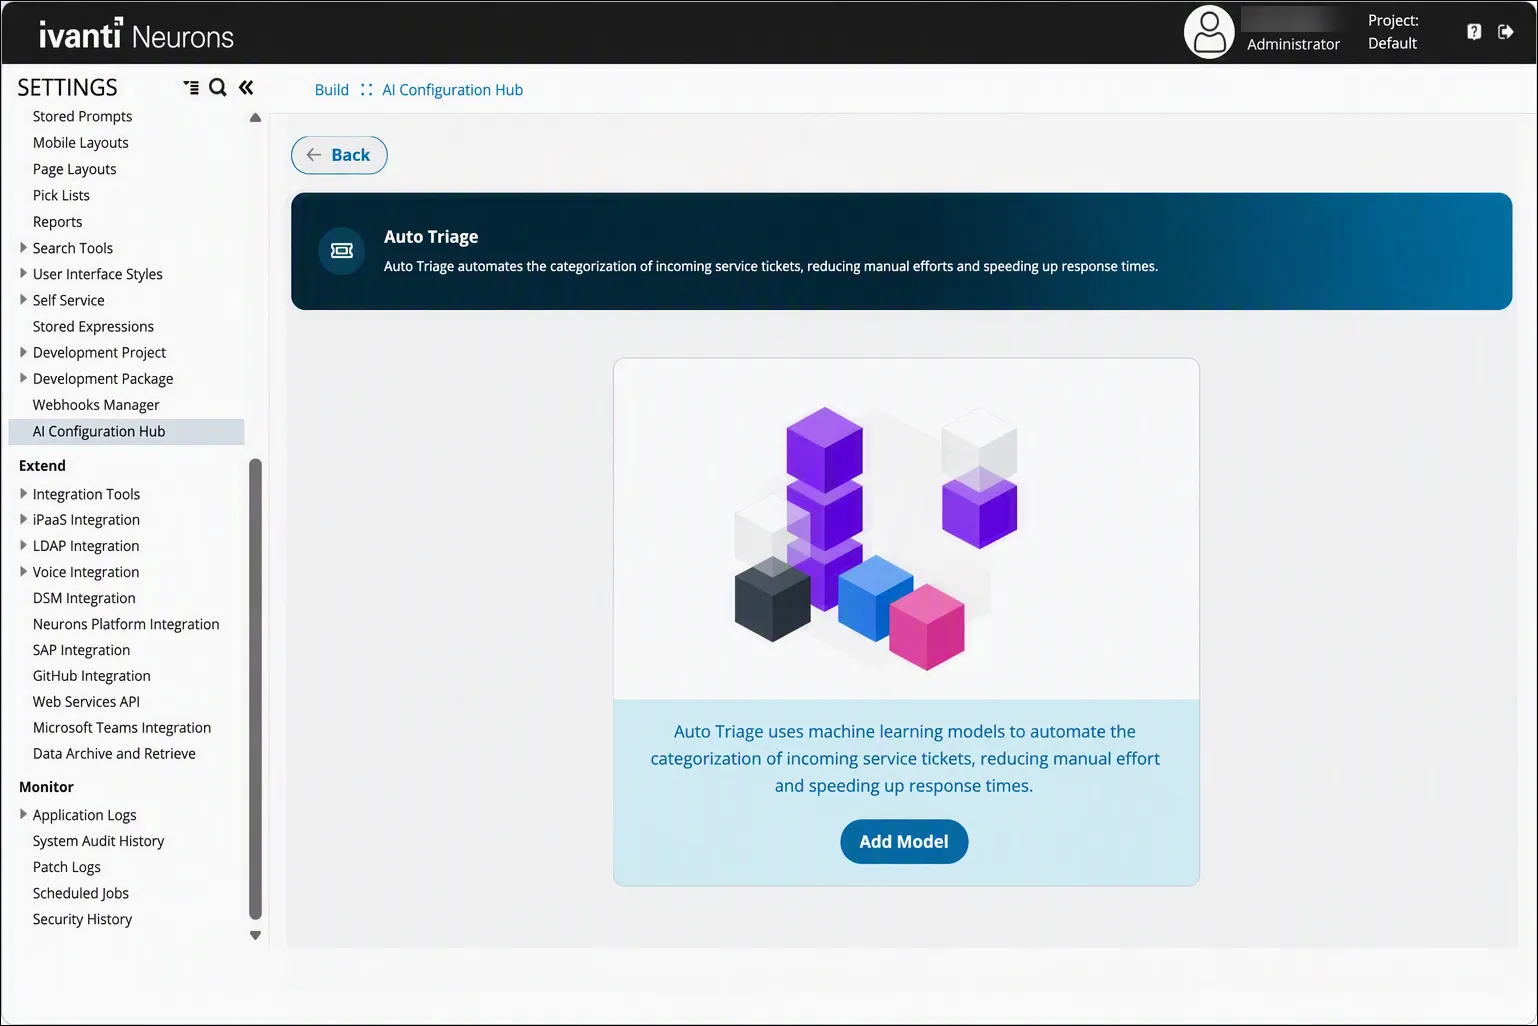
- Enter the Name, Description, and choose a Language.
The selected language is used for model identification only. The model is multilingual, so it can process all supported languages, regardless of the language selected in this field.
- Set the Threshold Percentile value to determine how confident the model must be before it accepts a predicted value for an Output Field.
You can choose a value between 10% and 90%, in increments of 10%. Setting a lower value makes the model recommend Output Field values more frequently, although some recommendations may have lower confidence. A higher value makes the model recommend Output Field values only when it is more confident that the prediction is correct.
This setting is configured separately for each Output Field and can be changed at any time without retraining the model.
- Set the Historical training data range so that the ML model is trained using records from the specified date range.
The selected date range determines which historical records are exported to the training dataset. The model does not apply any additional date-based filtering during training because no date cutoff exists in the training process.
Model training requires sufficient historical incident data. At least 10,000 records must remain after preprocessing, which removes incomplete or low-quality records and rare labels with fewer than approximately 200 examples per class. To help meet this requirement, start with approximately 15,000 to 20,000 resolved or closed incidents and include additional records for categories with limited data.
Your raw incident count does not need to be exactly 10,000. Before training, the system cleans each ticket's text by removing HTML, links, ticket numbers, and punctuation, leaving only meaningful words. A ticket that contains only placeholder text, such as Resolved with an empty description, might be reduced to a single word and excluded because it does not provide enough information for the model to learn from.
Because many tickets are reduced or removed during preprocessing, plan your raw dataset to be well above 10,000 records, typically 15,000 to 20,000 resolved or closed incidents.
Example: <p>User cannot log in to VPN</p> becomes user cannot log in vpn and is retained for training. In contrast, a ticket containing only Resolved becomes resolved, which provides insufficient information and might be excluded from the training dataset.
- If training fails due to insufficient data, increase the Historical training data range and retrain the model.
- If increasing the date range does not help, consider consolidating rarely used categories into broader categories, where appropriate. Categories with very few examples (typically fewer than 200) are removed along with their associated tickets during preprocessing. Merging several low-volume categories into a broader category can help retain more data for training.
- The Incident business object is selected by default in the Select the Business Object dropdown.
- Under Input Fields, select the relevant fields to train the ML model.
When a Service Desk Analyst or Self Service User enters values in the selected Input Fields of an Incident record, the system predicts and populates the fields defined under Output Fields.
- You can add up to four entries.
- A field cannot be configured as both an Input Field and an Output Field.
- Use short-to-medium text or categorical fields, such as Summary and Description, as Input Fields. Avoid using lengthy or unstructured fields, such as Notes, Journal entries, HTML content, or attachment content, as they might affect model training.
- Under Output Fields, specify the fields that you want the ML model to predict and populate.
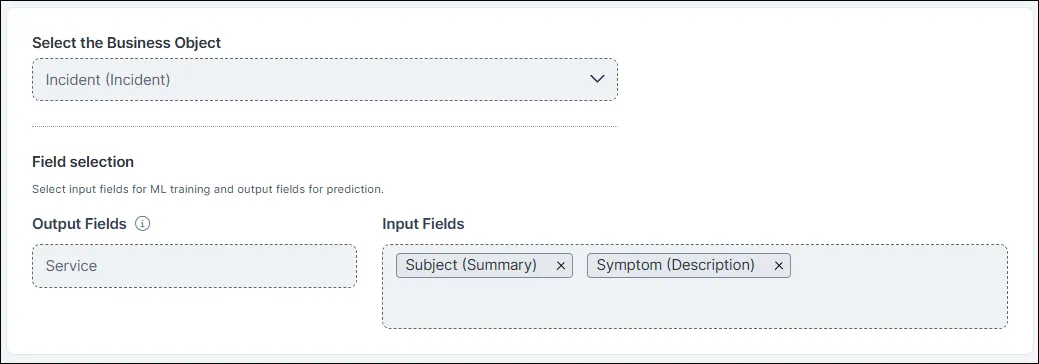
- Before training the ML model, ensure that the name of the fields selected under Input Fields and Output Fields matches your Incident business object field names. Some organizations might have customized field names in their Incident business object. For example, Sub-Category instead of Subcategory field. In such cases, you must create a field mapping so that the ML model can correctly recognize and use the custom field. For more information on field name mapping, refer to Viewing Fields.
- You can configure up to four Output Fields. Supported Output Fields are Category, Subcategory, Service, and Team.
- Turn on Enable Whitelist & stopwords filtering to enable it.
- Under Stop words, enter words or phrases that you want to exclude from the training data.
- Under Whitelisted keywords, enter the imported words to prioritize during classification.
- You can use a maximum of 20 keywords to both Stop words and Whitelisted keywords.
- Words separated by a space or comma are treated as separate keywords.
- Click Save to save the model as draft or click Save and train to train the model instantly.
- Click the Deploy icon
 to deploy the trained model once the model status change to Trained.
The model learns the fixed set of values available in its training data. Whenever you add, rename, or delete a picklist value used as an Output Field — Category, Service, Subcategory, or Team — you must retrain and redeploy the model. Until then, newly added values will not be predicted, and renamed or deleted values might still be recommended.
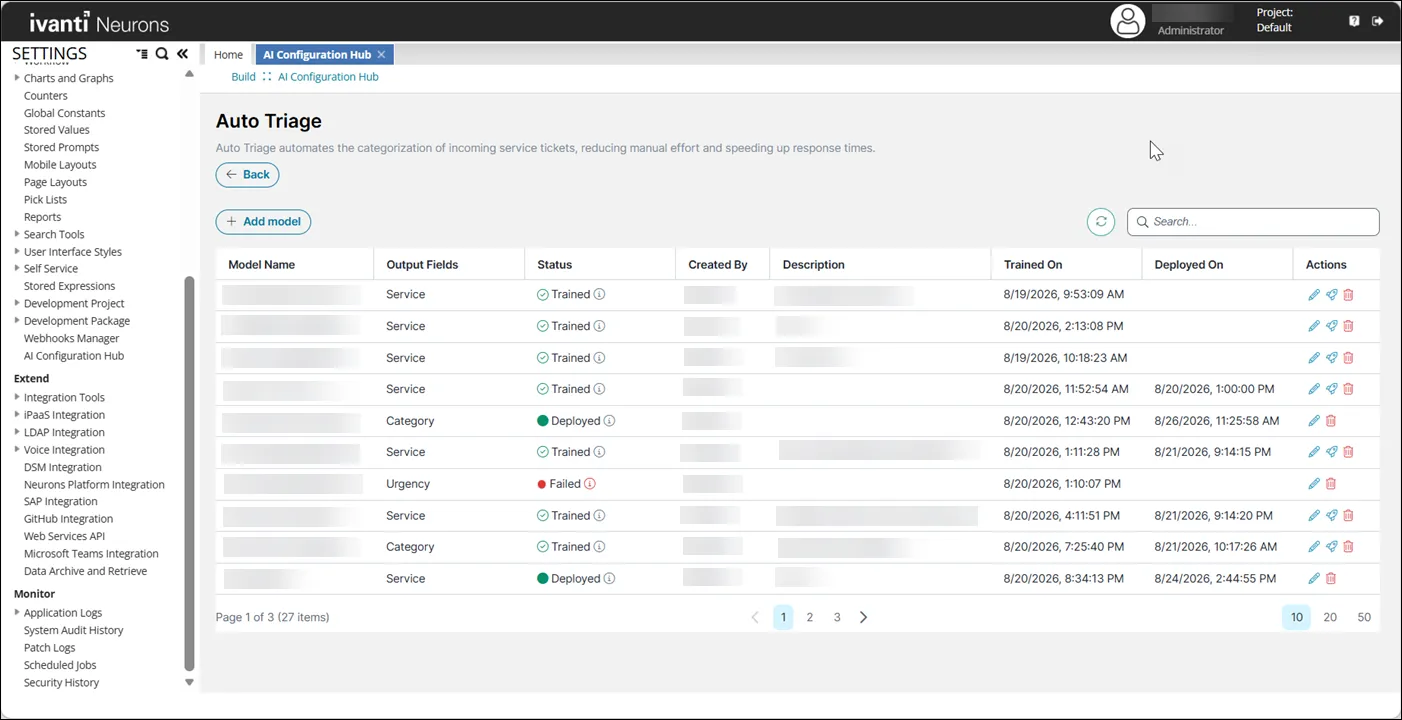
You can have multiple AI models with Trained and Draft status, whereas four models can be in the Deployed status simultaneously, one for each Output Field: Service, Category, Subcategory, and Team. For example, if you deploy another model with the Service field configured as an Output Field, the previously deployed model for the Service Output Field changes its status to Trained.
Steps 16 to 20 are applicable only if you are configuring the feature for Self Service Users. These steps are not required for Service Desk Analyst role as the AI prediction works automatically for Service Desk Analyst role.
- Go to the Configuration console > Build > Business Objects, and open Incident.
- Click Quick Actions tab, and then click Graphical Action Designer.
- Create a Quick Action using the AI Prediction Notification block. For more information, refer to AI Prediction Notification.
This quick action enables the ML model to predict and populate the values for the Output Fields that you configured in the AI Configuration Hub.
- After saving the Quick Action, go to the Business Rules tab and expand Triggered Actions.
- Ensure the Auto Triage action toggle is ON.
- For out-of-the-box customers, this toggle is ON by default. The Upgraded Customers must create this toggle using the + Add Trigger option. For more information, refer to Creating a Triggered Action for a Business Object.
- The feature predicts output field values even when incident records are created through email.
Configure the label
When Service Desk Analyst or Self Service User has auto-populated the Output Fields, the application displays recommended field values in the mapped fields Output Fields and a green-colored label indicating that the recommendations have been applied.
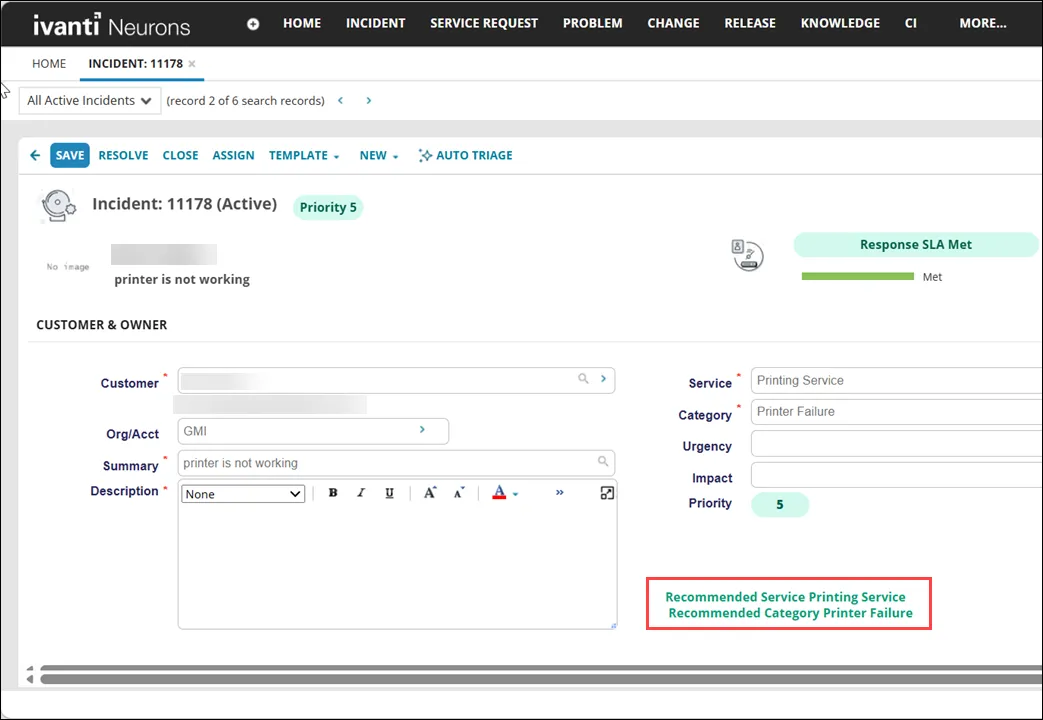
To display the label, do the following:
- Log in to Ivanti Neurons for ITSM as an Administrator.
- Open the Configuration console > Build > AI Configuration Hub > Incident business object.
- Click Forms tab and select the relevant form.
For example, Incident.CustomerOwnershipForm or any other form you use.
- Modify the form with the following expression:
$("AI Recommended Category "+RecommendedCategory) and $("AI Recommended Service "+RecommendedService)
For more information on modifying the form, refer to Using Forms.